My work connects multimodal learning with the environments in which it is used. I study agents and controllable generation alongside urban intelligence and physical modeling, and build systems that bring these ideas into practice.
01 · Visual generation & agents
Controllability, consistency, and generalization
LuckyShort · Agents for visual storytelling
ByFusion · Technical co-founder · 2025–present
At LuckyShort, I lead the development of video agents that coordinate script understanding, storyboarding, reference assets, generation, and visual quality evaluation. The central challenge is to keep characters, scenes, and story state consistent across many shots while giving creators control over the result.
Our systems combine long-context planning with reference-guided generation and local revision. They support commercial short-drama production, with content reaching more than 3 billion cumulative views across TikTok and YouTube. In collaboration with HKUDS, I also helped develop and release ViMax, an open-source project for agentic video generation.
I worked on post-training for the PixVerse V6 / C1 models, including multi-reference training data, preference data, reward design, and internal benchmarks. The work focused on identity preservation, controllability, and generation stability in video production workflows.
For multi-shot storytelling, different references may describe a character, clothing, or a setting. Keeping those conditions attached to the right shot is as important as matching their appearance. My work examined how to preserve identity while allowing deliberate changes in scene, motion, and camera transitions.
Generalization over Memorization
ACM MM 2026 Grand Challenge · Winner · RMB 210,000 prize
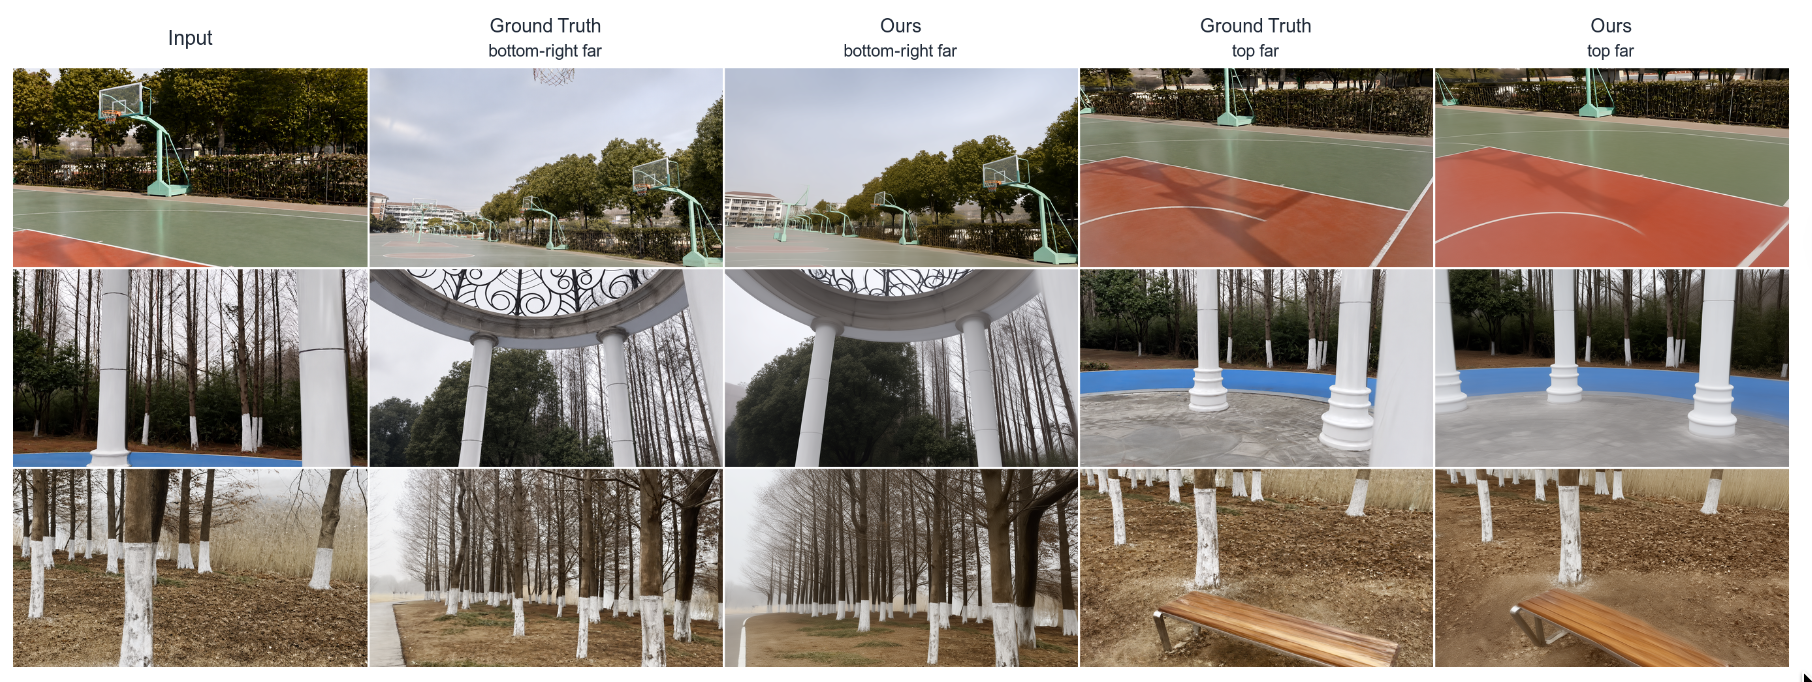
How can a generative model adapt to a small dataset without simply memorizing its scenes? Our work addresses single-image multi-view synthesis: generating 26 target views from one input image while preserving subject identity, spatial structure, and image quality.
With only 40 training scenes, we use scene-disjoint validation and lightweight adaptation of a 4B rectified-flow model. The method combines low-rank updates, training-trajectory control, and decoder adaptation to retain transferable pretrained knowledge. The final solution won the multi-view generation track, receiving a RMB 210,000 prize.
Input views and generated target views across different scenes. Open the figure to inspect the comparisons.
02 · Urban intelligence & AI for Science
Learning with spatial and physical context
Traffic-R1 · Reasoning for traffic signal control
ACL 2026 · Research at PCITECH
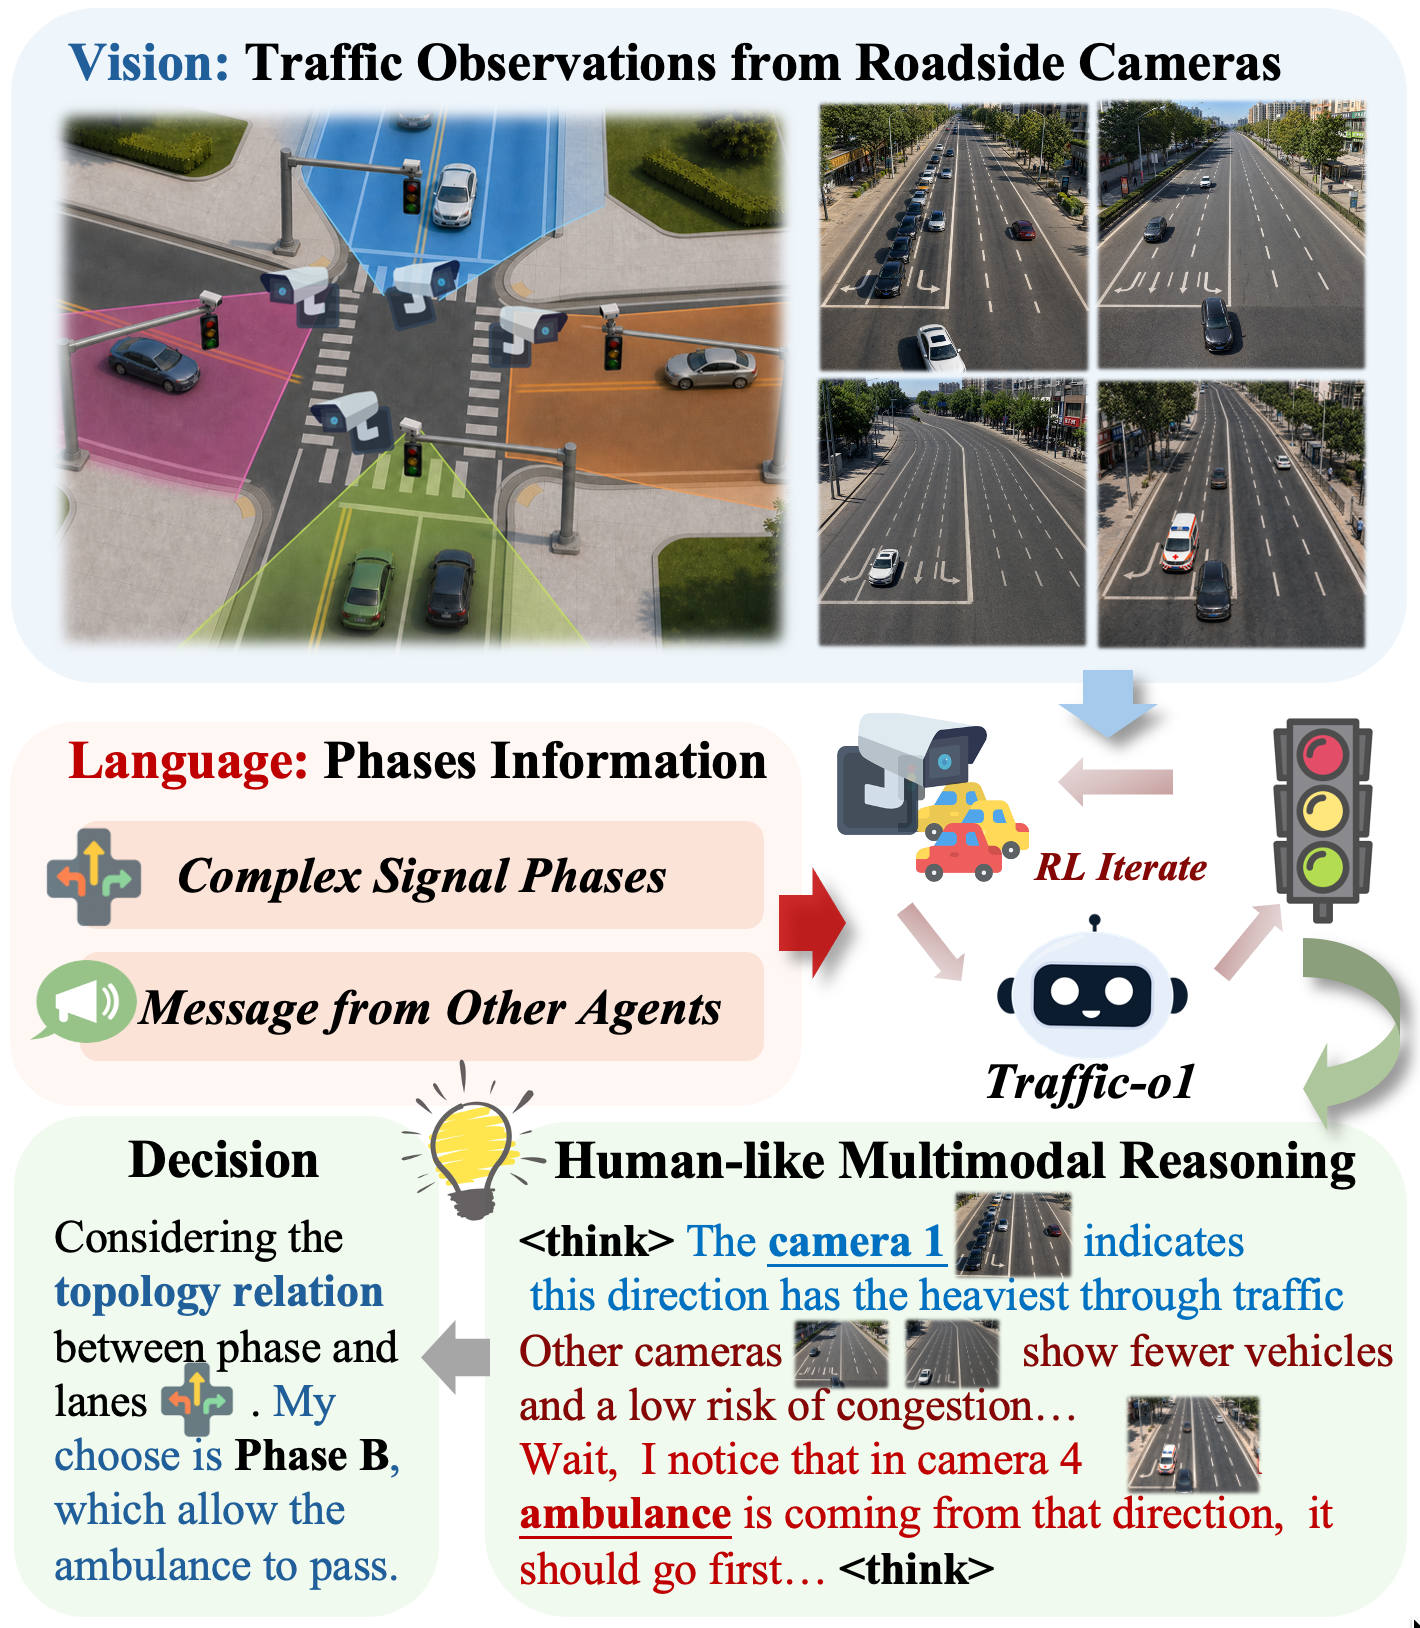
Traffic-R1 is a compact 3B-parameter reasoning language model trained with a two-stage reinforcement-learning framework. Human-informed offline training establishes a useful control prior; online interaction then aligns reasoning and actions with longer-term traffic outcomes.
The model reasons over road observations, incidents, and neighboring intersections. We study transfer to unseen road networks and unexpected events, connecting interpretable decision-making with practical control. This work was published at ACL 2026.
Traffic-VL · Grounding perception, reasoning, and action
Manuscript
Traffic-VL extends this line of work toward end-to-end control with vision-language models. Instead of relying only on a textual summary of an intersection, it grounds reasoning in visual observations and connects those observations to valid signal actions.
The work combines traffic simulation, varied visual conditions, and explicit lane-to-phase correspondence. This helps a model relate what it sees from different viewpoints to the road movements a signal can control. The goal is a consistent loop from visual evidence to reasoning, action, and environmental feedback.
DeepUHI · Urban heat-island forecasting
KDD 2025 · Oral
DeepUHI combines deep learning with thermodynamic domain knowledge for fine-grained, street-level urban heat-island forecasting. Physical context guides the model toward accurate and interpretable temperature predictions.
We also introduce SeoulTemp, a fine-grained urban-temperature dataset with 947 stations across 605 km² of Seoul over 2021–2024. This work reflects my continuing interest in using AI to understand the physical processes that shape cities.
GeoHG learns geospatial region representations by bringing satellite-image features together with points of interest and socioeconomic information. Its heterogeneous graph structure captures relationships that are difficult to represent with a single data source.
The work studies transfer across regions and inference where labeled data is limited. It was published as Space-aware Socioeconomic Indicator Inference with Heterogeneous Graphs.
At HKUDS, I worked on UrbanGPT and its multimodal extension, UrbanGPT-o, jointly modeling time series, language, and visual information. This research connects satellite imagery, mobility trajectories, graph structure, and socioeconomic signals for urban understanding and prediction.
My survey, Deep Learning for Cross-Domain Data Fusion in Urban Computing: Taxonomy, Advances, and Outlook, organizes this broader area by data, methods, and applications, including the role of large language models. It appears in Information Fusion.
Before my current work on agents and generation, I studied how data-driven methods could support construction, infrastructure, and the built environment.
Learning from rock-joint geometry
A non-contact workflow using 3D scans and convolutional networks to quantify rock-joint roughness and predict shear strength. Supervised by Dr. Qi Zhao, this study marked an early transition from physical experiments toward data-driven modeling.
Worker posture and ergonomic assessment
A CNN-LSTM model estimates Rapid Entire Body Assessment (REBA) scores from smartphone sensor data collected from construction workers. The work explored scalable posture monitoring without dedicated instrumentation, under the supervision of Dr. Yantao Yu.
JBOT · Robotics for construction
As a co-founder of JBOT (HK) Limited, I helped develop a computer-vision-guided robot for large-scale waterproofing. The project brought mechanical design, visual alignment, and on-site perception and control into an IoT-enabled construction system.
Bridge temperatures in a changing climate
My HKU graduation research combined Shenzhen Bay Bridge monitoring data, Hong Kong Observatory records, and calibrated finite-element thermodynamic models to study extreme bridge temperatures. Supervised by Prof. Francis T. K. Au and supported by the Architectural Services Department of Hong Kong, it informed recommendations for long-term structural performance.